
Table of Contents
Keywords: Salps; Game Theory; Diel Vertical Migration; Salp Swarm Algorithm; Optimization
Abstract
Salps are transparent, filter-feeding marine organisms that swim together connected via attachment plaques on the surfaces of their bodies to form multi-organismal chains. Shallow waters provide better food availability for salps in the form of phytoplankton, though inhabiting shallow water when sunlight is high presents a risk of predation by visual predators. Thus, salps display a dramatic change in water depth at dawn and dusk called diel vertical migration, migrating to the shallow layers during nighttime and to deeper layers during daytime. The strategy of diel vertical migration and the distribution of salps and predators can be predicted using game theory models. The superorganism collective ability of salps to explore and exploit an area for food can be modelled by mathematical equations called the Salp Swarm Algorithm (SSA). This metaheuristic model can mimic the salp swarming behaviour that was developed through evolution to optimize a salp’s ability to search for food. Flaws within the original algorithm include lower bound problems, a bias towards the origin, and inaccurate Newtonian physics. These flaws have led to improvements of the original SSA such as the Multi-Strategy-Driven Salp Swarm Algorithm (MSD-SSA) model.
Introduction
Salps consume phytoplankton as their main energy source by intaking seawater through an anterior siphon and consuming particulates in the seawater caught in its mucus filter. They can consume a variety of particles that are over three orders of magnitude (micron-sized to millimeter-sized), and their rate of filter feeding is so high that it can lead to over-grazing of primary producers in a region of water (Henschke et al., 2016). Due to having high grazing efficiency and energy efficient swimming mechanisms, salps serve as a nutritious food source for predators that include several species of fish, turtles, seabirds, and marine mammals such as the ocean sunfish (Mola mola) and leatherback turtle (Dermochelys coriacea). The dominance of salp genetic material in analyses of marine predator scat indicate that salps are not just a food source, but targeted prey for some species (Cavallo et al., 2018).
In response, several salp species such as Weelia cylindrica display a pattern of moving vertically in the ocean throughout the day cycle in avoidance of predators, known as diel vertical migrations (DVM). These species tend to move into deep water in the daytime and rise to shallower water during nighttime (Mackie, 1986). Such mechanisms are hypothesized to be related to the brightness of light: brighter light allows for greater phytoplankton concentrations due to greater rates of photosynthesis while also presenting a greater risk of being seen by predators. During nighttime, the phytoplankton concentration in the shallow layers remains high, though the risk of predation decreases due to a lack of sunlight illuminating the water. With diel vertical migration, salps can consume considerable amounts of phytoplankton in the shallow layers at night and avoid the notice of visual predators in deeper waters during daytime.
Along with this migration pattern, salps also adapted a superorganism behavior where they form long chains of salps to optimize their feeding (Fig. 1). Using collective intelligence, salps can better forage and explore the space around them in a more efficient manner than if they were individuals (Castelli et al., 2022). This is an important design strategy for filter feeders as they must search for their food constantly, especially for a species that has minimal defense mechanisms. This swarming action can be mathematically modelled into algorithms and used for other optimization problems. Overall, the diel vertical migration and the swarm technique are useful tools for salps to avoid predators and maximize their feeding efficiency through collective movement. Unified salp aggregation and their methodical movement patterns lead to better survival.

Fig. 1. Shape of a) a solitary salp and b) a salp chain (Ebrahim et al., 2022).
Game Theory
Game Theory in Biology
Game theory is an analysis concept that originated in the study of economy, later applied to biology to explain the phenomenon of unique behaviors that have frequency dependency (Leimar & McNamara, 2023). Several scientists, such as Ernst Zermelo, John von Neumann, and John Nash, the father of game theory, contributed to the development of this subject. In game theory, the entities that take action to affect each other are called players (in biological cases, organisms such as salps and fish are players). Non-cooperative game theory refers to instances in which players cannot communicate or make binding agreements (Bonanno, 2024). Cooperation, contest, signaling, and many other concepts can be modeled with game theory, such as the evolutionarily stable strategy (ESS) introduced by J. Maynard Smith and G. R. Price (Leimar & McNamara, 2023; Smith & Price, 1973).
The ESS model is a case of Nash equilibrium (named after John Nash), where players are satisfied with their choice after knowing the opponent’s choice. In other words, a Nash equilibrium arises when neither player changes their current strategy, as doing so will not improve the result in that player’s favor (Bonanno, 2024; Leimar & McNamara, 2023). The ESS seeks a stable endpoint of evolution, denoted as x*. For a monomorphic organism (where most populations follow the same strategy), the original strategy is denoted as resident strategy x, and the mutant strategy is referred to as x’. If strategy x fits all Equations (1), (2), and (3), it is viewed as the stable endpoint x*:


W(a,b) refers to the fitness of the strategy a to b, and F(x) is a partial differentiation of x's fitness with respect to x’. Fitness measures reproductive success (how many offspring are produced to carry the genome), is calculated based on the costs and benefits of the strategy (Leimar & McNamara, 2023; Orr, 2009). Equations (1) and (2) describe scenarios where x’ is less effective or of the same effectiveness as x*, so under the influence of natural selection x* will be the best-fit solution and thus become the ESS. Equation (3) illustrates where the species deviated from its most stable pathway due to environmental effects and re-evolved back to x* by natural selection (Leimar & McNamara, 2023).
Salps anticipate encountering various predators, among them, fish are one of the most prevalent predators that target salps (Heron et al., 1988). Thus, applying game theory models such as ESS through the lens of salps and fish as monomorphic organisms is beneficial for analyzing salp-fish interactions.
Simple Model for Salps and Fish Populations
Salps avoid visual detection from predators with their transparent bodies, and they travel into deeper, darker waters during the daytime to prevent sunlight from reflecting off their tunics and rendering them visible. Iwasa (Iwasa, 1982) established an ESS model based on the efficiency of fish to catch salps. Lack of light can significantly reduce the capture efficiency of certain types of fish, so the model considers the increase in fish fitness with increased hunting ability under higher light intensity conditions (Diehl, 1988). The upper layer of water is denoted as i=1 while the lower layer of water is marked as i=2 (Iwasa, 1982). The fitness of a strategy is defined as the difference between growth rate and mortality rate. In this simplistic model, only the growth rate by feeding and mortality rate by predators are considered. The fish are presumed to have no predators, so the fitness of fish is calculated with Equation (4) only considering growth by feeding:

Where 𝜑F is the fitness of fish, αi is the predation efficiency, and Zi indicates the salp abundance at a certain water level. Generally, more light is available in the upper layers compared to the lower layers, so α1>α2. During the daytime when sunlight is present, the light intensity of the upper layer increases much more than the lower layer. Thus, the difference in predation efficiency between the top and bottom layers is much higher during daytime than nighttime (Iwasa, 1982). The fitness of the salps (φz) considers growth by feeding on phytoplankton as well as the mortality rate by salps, which is described in Equation (5):

where β is a coefficient for grazing and is constant, Pi is phytoplankton (food of salp) density, which is larger in the upper layer (P1>P2), Fi is the density of fish in the layer, and θ is the converting coefficient to link risk caused by fish with the loss of fitness of salps.
Equations (4) and (5) can be used to model the behavior of the players (fish and salps), where players choose the layer that maximizes fitness according to the ESS (Iwasa, 1982). Denote the total number of fish as Ft and salps as Zt, the relationship between the total population of each species and the number on each level can be represented in the following Equation Set (6):


Simply put, fish are either all in the top layer (i=1) or the bottom layer (i=2), unless fish fitness in both layers is equal, and fish are distributed. Salp population distribution can be modelled similarly, with Equation (5) replacing the relative term for organism fitness in Equation Set (6).


Using Equation Sets (6) and (7), a unique Nash equilibrium arises during daytime when both α1Z1=α2Z2 and βP1 - θα1F1 = βP2 - θα2F2 are true. Solving for each equilibrium solution using Ft = F1 + F2 and Zt = Z1 + Z2 in the above equations, the distribution of fish and salp population are defined in Equation Set (8a)

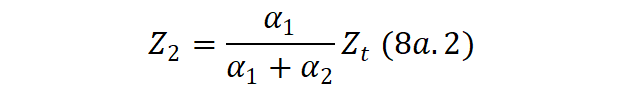


with Δ representing the critical point determining day or night phase. This critical point represents the benefits of feeding on the upper layer in the numerator and the risks of predation in the denominator.
Light intensity in the upper layer (α1) is always higher than the light intensity in the lower layer (α2) throughout the day, growing significantly higher upon the transition from nighttime to daytime. At a certain threshold value of light intensity in the upper layer, the distribution of salps suddenly changes according to Equation (7). Since the number of salps in the lower layer is proportional to the light intensity of the upper layer, increased light intensity during the day leads to a greater proportion of salps in the lower layer.
When light intensity in the upper layer is so low such that Δ>α1Ft, the number of fish in the bottom layer F2 is predicted to be negative by Equation Set (8a). This impossibility indicates that Equation Set (8a) is only valid when Δ≤α1Ft. In the case that F2=0, the equilibrium solution is described by Equation Set (8b):
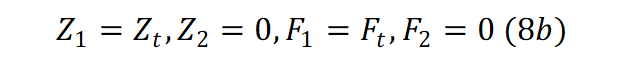
Thus, the Nash equilibrium in Equation (8a) happens during the day, when there's enough light in the upper layer so that Δ < α₁Fₜ. The equilibrium in Equation (8b) happens at night, when light is weaker and Δ ≥ α₁Fₜ, meaning the benefits of feeding outweigh the risk of being preyed on in the upper layer (see Fig. 2).
The solution for fish and salp population distribution Equations (4), (5) and (6) has a positive number of salps and fish in both layers during daytime. For an intuitive explanation for why not every salp travels to the lower layer in this daytime model, suppose the optimal strategy for all salps is to hide in the lower layer (Z1=0). The fish in the top layer will have no food, decreasing their fitness to be lower compared to fish in the bottom layer. Thus, all fish in the top layer will choose to move to the lower layer for better fitness, according to Equation (4). This causes predation risk for salps in the lower layers to increase. Mathematically, Equations (5) and (6) show that upon the fish population concentrating to the lower level (F2 =Ft), φZ1=βP1 and φZ2=βP2−θα2Ft, so φZ1> φZ2. The movement of all fish into the bottom layer causes the upper layer fitness of salps to increase, changing the salps’ optimal strategy from all hiding in the bottom layer to all escaping to the top layer. This contradicts the initial assumption that the best strategy is for all salps to hide in the lower layer during daytime. The Nash equilibrium only holds if players do not have a better solution after confirming the opponent’s choice. Thus, some salps will be in the upper layer during daytime, as shown in Fig.2 below (Iwasa, 1982).

Fig. 2. The number of salps and fish due to predation efficiency. The shaded region reveals the distribution of salps, and the blank white region represents the distribution of fish (Iwasa, 1982).
Diel Vertical Migration
According to Equation Set (8a), the proportion of salps and fish in the upper region during the day is:


Assuming the intensity of light in the lower layer changes proportionately with the intensity of light in the upper layer, α2 = γα1 where 0 < γ < 1 then Equation Set (9a) can be rewritten as:


Under this assumption that the light intensity of the lower layer has a linear relationship with the light intensity of the upper layer, the proportion of salps in the upper layer remains constant at γ / (1 + γ) during daytime, which is when the light intensity of the upper layer is above the threshold between day-night phases Δ / Ft . For fish behavior during daytime, the proportion of fish in the upper layer decreases towards γ / (1 + γ) as light intensity increases above the threshold (Fig. 3). The result is that salps make dramatic changes in population distribution via diel vertical migrations (DVM) at dawn and dusk, whereas predators make less conspicuous movements between the upper and lower layers (Iwasa, 1982).

Fig. 3. Proportion of salps in the upper layer as light intensity of the upper layer changes. At the threshold light intensity where night phase transitions to day phase, the salp population decreases in a stepwise function, whereas fish populations decrease more gradually (Iwasa, 1982).
Multi-layer Ocean Model for Predator-prey Interaction
The model for DVM proposed by Iwasa (Iwasa, 1982) is useful for comparing the migration patterns between salps and their predators (e.g. fish). However, the model by Pinti and Visser (2018), (Pinti & Visser, 2018). improves upon the model by Iwasa (1982) by considering the exponential decrease of light intensity with increased depth, migration costs, the number of daytime or nighttime hours, and more than two positions of depth in the water column. Let the water column be divided into N layers each D meters thick. Salps and predators have two choices that determine their strategy: which layer do they inhabit during daytime and which layer do they inhabit during nighttime. The day cycle is divided into a day phase with σ representing the fraction of the diurnal cycle that is daytime and 1-σ as nighttime.
Fitness for a player using a certain strategy of inhabiting layer i during nighttime and layer j during daytime is calculated by subtracting mortality from growth of that strategy performed by that player. The growth of salps and predators in this model considers growth from consumption, which varies depending on a growth scaling factor, subtracted by a term for migration costs, which increases linearly with vertical distance migrated. The growth scaling factor varies by time spent in each layer (σ and 1-σ). Salp growth increases with greater phytoplankton concentration, while predator growth increases in layers with greater light intensity and greater proportion of salps in the same layer at the same time. The mortality risk of salps increases with greater light intensity and predator concentration in the same layer at the same time stage. Predator mortality increases with greater predator concentrations, mimicking interference and competition between individual predators.
A Nash equilibrium for population distribution is achieved when all populated strategies have the same fitness. Due to the introduction of more possible strategies due to the water column that can be divided into arbitrarily many layers, more parameters than light intensity affects the strategies of each player in Nash equilibrium.
Variation in Maximum Predation Rate
As maximum predation rate bmax varies, three different predator-prey strategies arise at low, intermediate, and high bmax. At small bmax (bmax <0.02), predators and prey stay in the surface layer and exhibit no significant vertical migration. The population distribution is more dispersed during the daytime and more concentrated during nighttime for both populations.
At intermediate bmax (0.02<bmax <1.6), DVM can be observed favoring migration towards deeper levels during daytime as bmax increases, though very concentrated with prey and more dispersed with predators. The dispersal of predators prevents the equilibrium from breaking by preventing a back-and-forth of the favorable choice constantly changing with predator chasing prey and prey avoiding predator as explained with the Iwasa model. In both the small and intermediate stage, prey fitness decreases, and predator fitness increases as bmax increases, though predators experience a fitness drop upon transitioning to the intermediate phase due to DVM reducing their predation rate.
For large bmax (bmax >1.6), prey concentrate at the deepest levels without vertical migration, and predators are uniformly distributed throughout the water column. The fitness for predator and prey drop to zero upon entering this stage due to inefficient feeding and growth for both players. These strategies and the fitness correlating to each strategy at each phase relating to maximum predation rate are shown in Fig.4.

Fig. 4. Vertical distribution and fitness of prey and predator at different times of day with varying maximum predation rate. Dashed lines indicate the threshold between small, intermediate, and high bmax stages. (A-D) Population distribution at different vertical positions is indicated with darker colors for greater concentration of prey or predator. (E-F) Variation of fitness is calculated according to the overall fitness of all players whose choices are demonstrated in (A-D) (Pinti & Visser, 2018).
Variation in Daytime Hours
Variation in daytime fraction σ also results in varying DVM strategies, reflecting seasonal changes in salp migration patterns in polar regions such as the Southern Ocean, where there is a large population of salps. For most values of σ (0.1<σ<0.9), predator and prey vertical distributions display little variation. However, at extreme values of σ, the energy cost of vertical migration is not worth it for the small amount of time spent on another layer. If σ is small (σ<0.1), prey stay near the surface with minimized risk of shorter daytime, and predators likewise stay near the surface. If σ is large (σ>0.9), prey stay deep, and predators disperse evenly in the water column (Fig.5).
This pattern matches field findings of krill and their predators in the Mediterranean, which normally perform diel vertical migration, not performing DVM during the summer due to changes in daytime hours (Pinti & Visser, 2018). Unfortunately, given the difficulties of studying pelagic ecosystems, a similar study has not been performed on salps.

Fig. 5. Vertical distribution and fitness of prey and predator with varying daytime fractions. (A-D) Population distribution at different vertical positions is indicated with darker colors for greater concentration of prey or predator. (E-F) Variation of fitness is calculated according to the overall fitness of all players whose choices are demonstrated in (A-D) (Pinti & Visser, 2018).
Salp Swarm Algorithm (SSA)
What is SSA?
While salps can feed in their solitary life stage, they tend to form aggregates connected to other salp individuals during their sexually reproducing stage. When food is abundant, the population of salps can grow quickly, leading to dense swarms (Henschke et al., 2016). In other words, salps are barrel-shaped tunicates that form long chains actively looking for phytoplankton. The individuals making up the chain follow the front leader salp who is performing space exploration for food and optimal regions to exploit (Castelli et al., 2022). The salp swarm behaviour is said to achieve better foraging and locomotion from rapid coordination changes and optimizing kinetic energy throughout the foraging process (Yang et al., 2020).
Swarm intelligence is a concept that involves the collective intelligence of a group of autonomous individuals in a self-organized environment. A swarm uses the cooperation and interaction of individuals that have voluntarily converged to work towards a common goal. The collective behaviour of the swarm is said to have a higher intelligence level beyond that of each individual member’s intelligence (Sadiku & Musa, 2021). This can lead to predictable patterns and optimized performances from the global behaviour and adaptability of the swarm. The Salp Swarm Algorithm (SSA) is a tool used to mimic the collective behavior of salps to solve optimization problems. This involves a metaheuristic algorithm, meaning a mathematical equation, that solves optimization questions by mimicking natural phenomena.
There are two main types of Salp Swarm Algorithm (SSA); the first being evolutionary algorithms and swarm intelligence techniques as seen with the SSA tool. Other examples of algorithms of collective behaviour can be seen with ants, where the Ant Colony Optimization algorithm mimics the ant's ability to find the shortest path between home and food (Mirjalili et al., 2017). To mathematically model SSA, the population must first be divided between the leader and the followers. The leader is at the front of the chain and guides the followers in the swarm (Mirjalili et al., 2017). An illustration of a salp chain is show in Fig. 6.

Fig. 6. A salp chain with the leader salp and the follower salps (Faris et al., 2020).
A summary of Mirjalili et al.’s (Mirjalili et al., 2017) model is presented below. The position of salps can be described in n-dimensions, where n is the number of variables, in this case the number of salps considered. In a 2D matrix called x, the position of the salp leader can be described by Equation (10), where there is a food source (F) that is the swarm’s target.


Here, xj1 represents the position of the leader salp, Fj is the position of the food source in, ubj indicates the upper bound of jth dimension, lbj indicates the lower bound of jth dimension. The coefficients are random numbers, where c2, and c3 are randomly generated numbers between 0 and 1 that represent the step size and whether the next position will be in the positive or negative direction respectively. The coefficient c1 balances exploration and exploitation and is also randomly generated with Equation (11).

L is the maximum number of iterations and l is the current iteration.
Then, to update the following salp positions, Newton’s law of motion is used seen by Equation (12).

xli is the position of the ith follower salp in the jth dimension, t is time, v0 is the initial velocity and a the acceleration. However, for an optimization algorithm, time is measured in iterations (equal to 1) and the initial velocity = 0 for the salp chain. This leads to Equation (13) being used for the model:

The swarm simulation performed by Mirjalili et al. (Mirjalili et al., 2017) used 20 salps randomly placed around a stationary source of food. The behaviour of the salp swarm position was analyzed in 2D and in 3D over the span of 9 iterations seen in Fig. 7. The blue cross is the food source; the darkest dot is the leader salp and the gradient of grey dots are the following salps in the swarm (Mirjalili et al. 2017).

Fig. 7. Salp chain movement around a stationary food source in 2D and in 3D.
The simulation shows that the salps effectively move across the space to explore and exploit the area around the food source. The movement of the first salp has abrupt changes in the initial iterations, then more gradual and monotonous behaviour towards the final steps. This SSA observation indicates that the model first requires the salps to search the space, driving them to move towards a collective goal by exploring locally instead of globally. In other words, salps will explore a local area as a unit, rather than explore a larger space as individuals. To confirm the optimization of this behaviour, the average fitness of all salps and the convergence curve (the improvement over time towards the optimal solution) was analyzed. There was a descending trendline found for both, which for a minimization problem, prove that the quality of the swarm increased with the number of iterations. The initial exploration does have a deterioration of fitness as the salps move with sudden random changes, but this is smoothed out and decreases proportionally to the iteration number (Mirjalili et al., 2017). The findings of the displacement trajectory of salps, the average fitness curve and the convergence curve is represented by Fig. 8.

Fig. 8. Three model runs representing the trajectory in yellow, the average fitness of all salps in red and the convergence curve in blue.
Overall, the findings of Mirjalili et al. (Mirjalili et al., 2017) show that the SSA model is a promising tool to model the exploration of space and was able to move salps abruptly in the first stages of iterations, but gradually in the final stages, improve the average fitness of all salps as a collective and effectively find optimal solutions with high convergence and coverage. The modelling of this collective intelligence and swarm behaviour can therefore be used to solve optimization problems found in the real world. For example, machine learning, spatial problems, feature selection, spam detection systems, and optimizing neural networks to name a few (Faris et al., 2020).
Deconstructing and Critiquing SSA
Though SSA has been adapted to solve many types of optimization problems, the inherent design of the algorithm isn’t devoid of flaws. Upon review the original Mirjalili et al. (Mirjalili et al., 2017) paper and associated algorithms, Castelli et al. (Castelli et al., 2022) noticed the following problems with the original SSA:
First, when the lower bound is non-zero for any dimensions explored by the leader salp, the update rule for said leader salp causes unintended behaviors.
Second, SSA has a bias towards the origin, which could be useful if the optimum was close to the origin but that is not always the case.
Third, the updating rule of the follower salps was derived inaccurately from Newton’s laws of motion.
These flaws are carried onto many works based on SSA, potentially leading to the systematic skewing of results, the extent of which is still undetermined.
Leader salp updating rule flaw
Look at the Equation (10) again below:


Here, in layman’s terms, along a specific dimension j, the leader salp decides to either move in the positive direction or the negative direction from an initial point F. This movement is decided by the c3 term which is generated randomly from range [0,1]. Those with keen eyesight would notice that, following this rule, the leader salp would always move positively across all dimensions because c3 is always bigger than zero! The original algorithm proposed by Mirjalili et al. (Mirjalili et al., 2017) averts this problem by having the threshold for determining whether the leader salp should move positively or negatively be established at 0.5 instead of the 0 mistakenly shown in their paper. What is more concerning about this misprint is that many subsequent papers referencing Mirjalili et al. (Mirjalili et al., 2017) repeat the same error, many of which are listed by Castelli et al. (Castelli et al., 2022). Thus, all algorithms with this flaw must start their search from the origin towards the positives in all dimensions, or else they would miss out on unexplored data points.
Another issue with the lower bound involves the set-up of the upper bound (ub) in relation to the lower bound (lb) for a given searchable dimension j when lb is much larger than the search area (lb >> (ul – lb)). Under these conditions, the search area for the given dimension (ub – lb) will become negligible in comparison to the overwhelmingly larger lb and the leader salp will endlessly clip into the boundaries. Either c1 becomes small enough for the search area to make a difference or the search iterations end. The former would not cause much issue, but the latter will render the results for this dimension useless as the salp leader would end up on the boundary instead of the optimal position. However, as a note, the case of SSA stopping due to an overwhelmingly large lb only occurs as the lower bound would have to be several orders of magnitude greater than the search area for c1 to be rendered ineffective for all search iterations.
Bias towards the origin
From the experiments by Castelli et al. (Castelli et al., 2022), it was discovered that, on a symmetric search space, SSA will have a bias towards the origin. To be performant, SSA is supposed to either wander the search space aimlessly in search for the optimum or slowly converge towards the food attractor, if they exist, while looking out for possible optima. However, in practice, the salp swarm seem to converge towards the origin, as shown in Fig.9. Normally, we would expect SSA to spread out when there are no food attractors, but the figure clearly suggests that isn’t the case. Rather, it seems that SSA favors problems whose global optimum lies near the origin. This could possibly lead to sub-optimal performances for the application of SSA and undermine the usefulness of SSA.

Fig. 9. Though start areas are different, the leader is attracted to zero while the swarm moves towards the origin of axis. SSA is equal to SSO in the figure (Castelli et al. 2022).
Flawed physics
Upon reviewing the original Mirjalili et al. 2017 paper on SSA, Castelli et al. 2022 discovered that parts of the physics used to justify the behavioral modelling of follower salps was inaccurate, specifically Equation (12).

For one, acceleration was defined as a = vfinal/v0 when the actual equation is a = (v(t+Δt) - v(t)) / Δt. From the survey of literature conducted by Castelli et al. (2022), this definition of acceleration is not always corrected. Other flawed or simplified physics used to model follower salps using Newton’s laws of motion include using average speed instead of instantaneous velocity to compute acceleration, follower salps with constant acceleration until infinity, and more which can be read in Castelli et al. (Castelli et al., 2022). However, though the physical motivations for the elaboration of the follower salps’ updating rule are weak, this does not necessarily decrease SSA’s effectiveness as a random search algorithm but rather puts into question the rigor needed for justifying the logic behind biologically based models. If hand-wavy physics is good enough to model salp movement and coordination, are we in a position to critique it? We will leave these thoughts behind for readers to contemplate.
Improvements of SSA
Despite critiques of SSA, research has shown that this tool can be enhanced and then applied in many different fields, such as optimization design, machine learning, and more. SSA has several shortcomings as an optimization model, but these shortcomings can be improved upon.
First, Salp Swarm Algorithm has low convergence accuracy, meaning that it does not achieve the optimal solution with a high degree of precision. For example, the salp chain cannot efficiently find the food source (Gao & Wang, 2023). SSA also has slow convergence speed, meaning that the algorithm takes many iterations to approach the best solution. In simple terms, SSA is slow to find the right food source. Finally, SSA easily falls into a local optimum, which is different from its tendency towards the origin. In optimization, local optima and global optima refer to points within a solution space that represent the best solutions, or "best food source" (F), only differing by the scope. A local optimum is a solution that is better than any nearby solutions, meaning it provides the best result within a limited region of the solution space. The global optimum, by contrast, is the absolute best solution across the entire solution space. For salps, the global optimum would be the best food source location within the entire ocean, which is the desired result for optimization problems. In SSA, the goal is to find this global optimum, however, during iterations, the algorithm might settle at a local optimum, believing it has reached the best point when a better, higher-value solution (the global optimum) may exist elsewhere in the solution space (Gao & Wang, 2023).
Therefore, much research has been conducted to improve the Salp Swarm Algorithm with modifications and additional optimization techniques applied to overcome SSA’s limitations and achieve more specific results so that salps can find the ultimate best food location.
The Multi-Strategy-Driven Salp Swarm Algorithm (MSA-SSA)
The Multi-Strategy-Driven Salp Swarm Algorithm proposed by Gao and Wang (Gao & Wang., 2023) is one of the improved versions of SSA. In standard SSA, the leader agents that guide the salp chain only update their positions relative to a food source. The followers then update their positions based on the leader's position. This setup can lead to problems if the leader becomes stuck in a local optimum, as it will not be able to explore beyond this point, causing all followers to get trapped as well (Neggz et al., 2020). To address this, MSD-SSA first introduces the Levy flight strategy for the leaders of the salp chain (Gao & Wang, 2023). Simply put, Levy flight strategy allows SSA to take larger and smaller steps randomly. In standard SSA, the leader only searches according to the food source’s location, so when the leader locates a food source, it gets stuck in the range of that food source and does not explore potentially better sources. By establishing the Levy flight that has accidental long-distance steps, it allows the salp chain to move further, expanding the search range and jumping out of the local optimum’s limits. At the same time, the random short-distance steps also enable careful search of the surrounding area and improve local exploitation ability. The trajectory of Levy’s flight as shown in Fig.10 is very random.

Fig.10. Movement trajectory of Levy flight: a random walk graph generated by Levy flight random step within a certain range and random direction walking. (Gao & Wang, 2023).
The probability density function of the Levy flight follows the Levy distribution, which can be expressed by Equation 14 (Gao & Wang, 2023). In the formula for the Levy distribution, the variable s represents the spatial or temporal variable in the distribution, while k serves as the integration variable, corresponding to the wave number or frequency component. The scale parameter β determines the width or spread of the distribution, and the stability parameter λ characterizes its shape. The formula describes a Fourier transform integral, where exp(-β|k|λ) functions as the characteristic function of the Levy distribution.

According to the Mantegna method, the random step of Levy flight can be expressed by Equation 15 (Gao & Wang, 2023).

where u and v are Gaussian distributions that satisfy the conditions in Equations 16 and 17 (Mantegna, 1994).


To support the Levy flight strategy, a Crossover Operator is applied to increase diversity in the leaders' positions, which improves global exploration in the early stage of the algorithm and reduces the risk of premature convergence to a local optimum (Gao & Wang, 2023).
Then, as the salp chain approach the optimal global food source (in the later iterations, as the convergence factor c1 decreases), the algorithm switches from Levy flight to Brownian motion for the leader’s position updates. Brownian motion, generated by Equation 18, introduces smaller, random movements, which help fine-tune the leader’s position as it approaches the global optimum (Gao & Wang, 2023).

This switch is intended to improve convergence accuracy since the smaller steps of Brownian motion allow for more precise adjustments around the optimum.
Finally, unlike standard SSA, where followers update their positions solely based on the previous individual, MSD-SSA introduces a method where followers consider the average position of the leaders, as described in Equation 19 where Avg xj is the average position of all the leaders in the j-th dimension and Nl is the number of leaders (Gao & Wang, 2023).

This approach directs followers toward the general area of the leaders, helping the algorithm converge faster by guiding the swarm more directly toward promising solutions (Gao & Wang, 2023).
These improvements optimize both global and local searches within the algorithm, balancing exploration, and exploitation functions.
Experimental Results
As seen in Fig.11, ten benchmark test functions were used to test and compare the algorithm's performance, showing that MSD-SSA has higher global convergence and faster convergence than the original algorithm as shown in Fig.12 (Gao & Wang, 2023). It also outperforms the original algorithm in terms of robustness (Fig. 12).

Fig.11. Ten benchmark test functions were used to test and compare the algorithm's performance (Gao & Wang, 2023).

Fig.12. Comparison using the 10 benchmark functions of the global convergence of MSD-SSA in blue, SSA in dotted orange and WPA in dotted line green (Gao & Wang, 2023).
MSD-SSA can be applied to problems requiring optimal solutions, such as optimizing design variables for the best performance in engineering or adjusting model parameters for the best predictions in machine learning (Gao & Wang, 2023).
Other examples
Many other enhancements to SSA have been proposed to improve its performance. For example, Thawkar (Thawkar, 2021) introduced a hybrid model combining Teaching-Learning-Based Optimization with SSA (TLBO-SSA) for breast cancer diagnosis. Neggz et al. (Neggz et al., 2020) integrated the Sine Cosine Algorithm to enhance exploration and diversity. Zhang et al. (Zhang et al., 2022) created Enhanced SSA, which leverages orthogonal learning and quadratic interpolation for local accuracy. The group later introduced chaotic initialization and differential evolution to create an updated algorithm able to prevent premature convergence (Zhang et al., 2023).
Conclusion
Salps are fascinating and underappreciated organisms, yet, like many others in the natural world, they offer profound lessons when we take the time to study them closely. In defense against visual predators, some species of salps undergo diel vertical migration when transitioning from daytime to nighttime and vice versa. Salps migrate into to deeper layers during daytime and shallow layers during nighttime. As a result, salps exploit the high concentrations of phytoplankton in the shallow layers of the water column when risk of predation is lowest, during nighttime, and reduce mortality risk by hiding in dark waters when risk of predation is highest, during daytime. In addition, salps' ability to explore and exploit an area by optimizing their collective behavior to find the best food source is a prime example of superorganism intelligence. By combining individual intelligence and behavior, salps can increase the fitness of the entire group by optimizing locomotion and feeding.
Diel vertical migration patterns can be modelled with the game theory by finding the evolutionary stable solution in which both players do not change their choice given the choices of the other player. Such modelling predicts the location of salps and predator density in different light conditions and offers proof of the formation of such behavior. The model for diel vertical migration derived from salp behavior may apply to other marine organisms such as krill and copepods that perform diel motion, which is ecologically significant for the transferral of nutrients towards deeper ocean layers.
Salps’ superorganismal intelligence and cooperation, consisting of their specific leader and follower strategy, is modeled in SSA. Overall, the swarming technique allows for salps to optimize their space exploration, movement, and foraging for food sources. Their ability to search locally for food as an aggregation is proven to be an efficient method to increase the group’s fitness. However, it remains unproven why this is the case, it is likely due to coherent communication between salps, rapid coordination changes and an improved energy distribution among the individuals. Research has shown that this metaheuristic model can be applied in various fields, such as optimization design, machine learning, and more. However, flaws within the original algorithm—including lower-bound problems, a bias toward the origin, and inaccurate Newtonian physics—can limit its efficiency. As a result, many improved versions of SSA have been developed, such as the MSD-SSA model, which utilizes the Lévy Flight system, Brownian motion, crossover mechanisms, and the mean distance between followers and the leader to enhance the algorithm's performance and better mimic salp behaviour.
References
References
Bonanno, G. (2024). Ordinal Games in Strategic Form. In Game Theory (3 ed., pp. 19-46). Kindle Direct Publishing. https://faculty.econ.ucdavis.edu/faculty/bonanno/PDF/GT_book.pdf
Castelli, M., Manzoni, L., Mariot, L., Nobile, M. S., & Tangherloni, A. (2022). Salp swarm optimization: a critical review. Expert Systems with Applications, 189, 116029.
Cavallo C, Chiaradia A, Deagle BE, McInnes JC, Sánchez S, Hays GC and Reina RD (2018) Molecular Analysis of Predator Scats Reveals Role of Salps in Temperate Inshore Food Webs. Front. Mar. Sci. 5:381. doi: 10.3389/fmars.2018.00381
Diehl, S. (1988). Foraging Efficiency of Three Freshwater Fishes: Effects of Structural Complexity and Light. Oikos, 53(2), 207-214. https://doi.org/10.2307/3566064
Ebrahim, M., Mohamed, R., Saied, E., Maksoud, S., & El Khashab, H. (2022). Salp Swarm Optimization with Self-Adaptive Mechanism for Optimal Droop Control Design. In. https://doi.org/10.5772/intechopen.97229
Faris, H., Mirjalili, S., Aljarah, I., Mafarja, M., Heidari, A.A. (2020). Salp Swarm Algorithm: Theory, Literature Review, and Application in Extreme Learning Machines. In: Mirjalili, S., Song Dong, J., Lewis, A. (eds) Nature-Inspired Optimizers. Studies in Computational Intelligence, vol 811. Springer, Cham. https://doi.org/10.1007/978-3-030-12127-3_11
Gao, Z. and Wang, B. (2023) Multi-Strategy-Driven Salp Swarm Algorithm for Global Optimization. Journal of Computer and Communications, 11, 88-117. https://doi.org/10.4236/jcc.2023.117007
Henschke, N., Everett, J. D., Richardson, A. J., & Suthers, I. M. (2016). Rethinking the Role of Salps in the Ocean. Trends in Ecology & Evolution, 31(9), 720-733. https://doi.org/10.1016/j.tree.2016.06.007
Heron, A. C., McWilliam, P. S., & Pont, G. D. (1988). Length–weight relation in the salp Thalia democratica and potential of salps as a source of food. Marine Ecology Progress Series, 42(2), 125-132. http://www.jstor.org.proxy3.library.mcgill.ca/stable/24827393
Iwasa, Y. (1982). Vertical Migration of Zooplankton: A Game Between Predator and Prey. The American Naturalist, 120(2), 171-180. https://doi.org/10.1086/283980
Leimar, O., & McNamara, J. M. (2023). Game theory in biology: 50 years and onwards. Philosophical Transactions of the Royal Society B: Biological Sciences, 378(1876), 20210509. https://doi.org/doi:10.1098/rstb.2021.0509
Mackie, G. O. (1986). From Aggregates to Integrates: Physiological Aspects of Modularity in Colonial Animals. Philosophical Transactions of the Royal Society of London. Series B, Biological Sciences, 313(1159), 175-196. http://www.jstor.org/stable/2396897
Mirjalili S, Gandomi AH, Mirjalili SZ, Saremi S, Faris H, Mirjalili SM. 2017. Salp Swarm Algorithm: A bio-inspired optimizer for engineering design problems. Advances in Engineering Software. 114:163–191. https://doi.org/10.1016/j.advengsoft.2017.07.002.
Neggaz, N., Ewees, A.A., Abd Elaziz, M. and Mafarja, M. (2020) Boosting Salp Swarm Algorithm by Sine Cosine Algorithm and Disrupt Operator for Feature Selection. Expert Systems with Applications, 145, Article ID: 113103. https://doi.org/10.1016/j.eswa.2019.113103
Orr, H. A. (2009). Fitness and its role in evolutionary genetics. Nat Rev Genet, 10(8), 531-539. https://doi.org/10.1038/nrg2603
Pinti, J., & Visser, A. W. (2019). Predator-Prey Games in Multiple Habitats Reveal Mixed Strategies in Diel Vertical Migration. The American naturalist, 193(3), E65–E77. https://doi.org/10.1086/701041.
Smith, J. M., & Price, G. R. (1973). The Logic of Animal Conflict. Nature, 246(5427), 15-18. https://doi.org/10.1038/246015a0
Sadiku MNO, Musa SM. 2021. A Primer on Multiple Intelligences. Cham: Springer International Publishing.
Thawkar, S. (2021) A Hybrid Model Using Teaching-Learning-Based Optimization and Salp Swarm Algorithm for Feature Selection and Classification in Digital Mammography. Journal of Ambient Intelligence and Humanized Computing, 12, 8793-8808. https://doi.org/10.1007/s12652-020-02662-z
Yang, Bo, et al. “A Critical Survey on Proton Exchange Membrane Fuel Cell Parameter Estimation Using Meta-Heuristic Algorithms.” Journal of Cleaner Production, vol. 265, 1 Aug. 2020, pp. 121660–121660, https://doi.org/10.1016/j.jclepro.2020.121660. Accessed 25 Dec. 2023.
Zhang, H., et al. (2023) Differential Evolution-Assisted Salp Swarm Algorithm with Chaotic Structure for Real-World Problems. Engineering with Computers, 39, 1735-1769
Zhang, H., et al. (2022) A Multi-Strategy Enhanced Salp Swarm Algorithm for Global Optimization. Engineering with Computers, 38, 1177-1203. https://doi.org/10.1007/s00366-020-01099-4.